Claude Fable 5.1 Draws a Python Reading a Book
Real Python AI
September 03, 2026 at 10:00 AM
📌 Claude Fable 5.1 takes Real Python's vibe check for AI models: a turtle drawing of a python reading a book, a Python vintage, a tiny edit, and a made-up function.
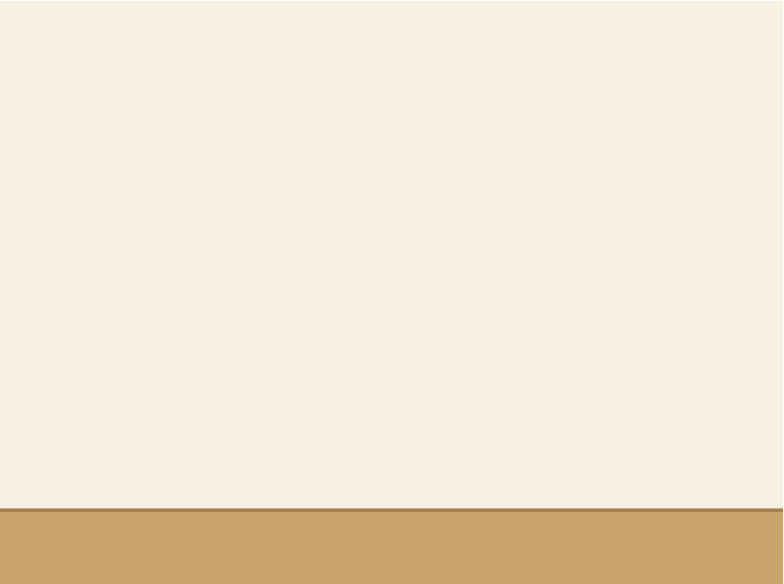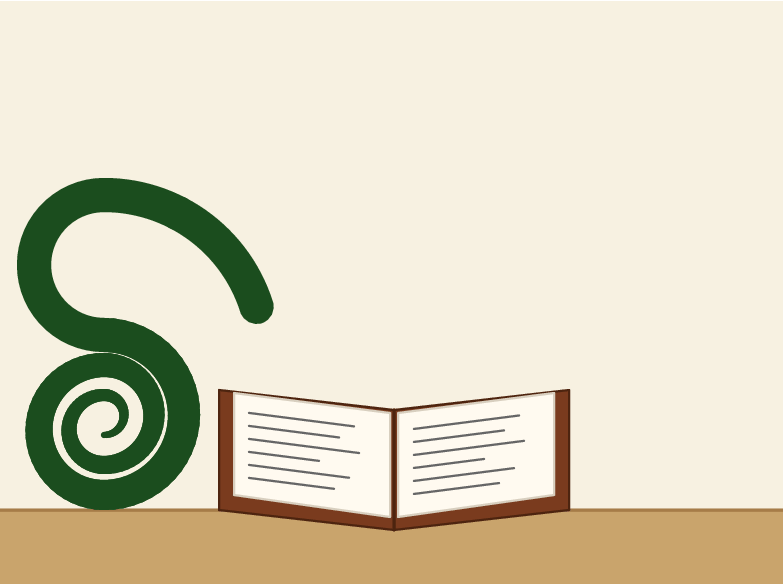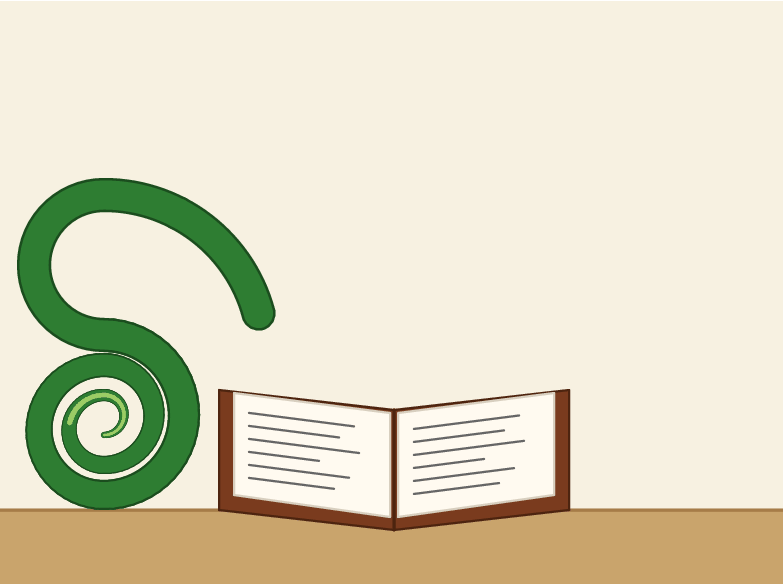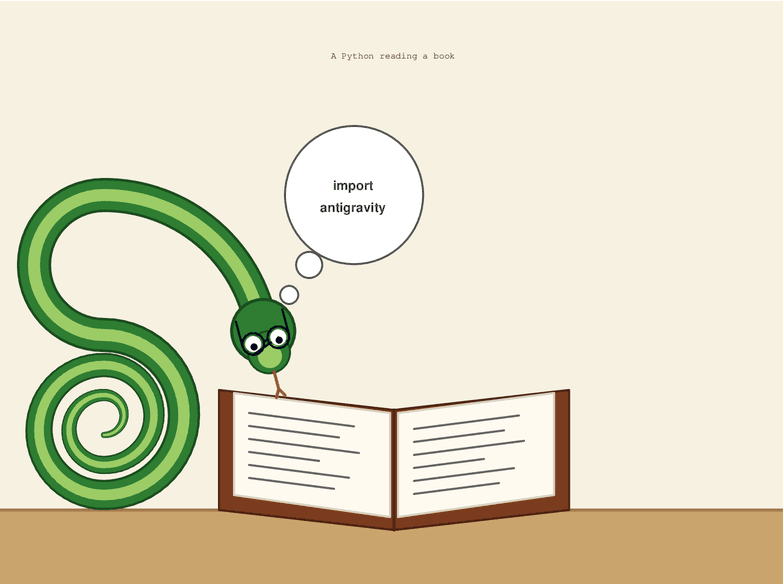
We ran Claude Fable 5.1 through Real Python’s vibe check for new AI models: five fixed prompts, one shot each. The first one is always the same line, “Write a Python turtle program that draws a python reading a book.” Here’s what Claude Fable 5.1 drew:
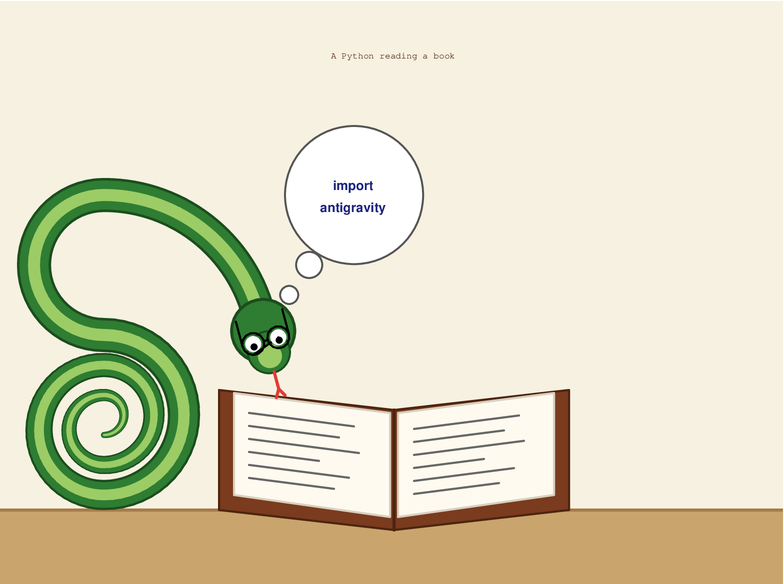
That’s task one of five, exactly as its turtle script drew it. The numbers for all five come next, then each task in detail.
Watch it drawShow/Hide
New here? What the five tasks measureShow/Hide
Every model gets the same five prompts, one shot each, no system prompt, and nothing is fixed up afterwards. Here is what each row in the results table means:
Task
What we ask
What we read off the answer
The snake
Write a Python turtle program that draws a python reading a book.
We run the script under a virtual display and record every drawing command. The picture is whatever came out, arrow and all.
How modern its Python is
Write a small command-line tool from a fixed spec.
Which idioms it reaches for: list[str] or typing.List, tomllib or a hand-rolled parser, Path.walk() or os.walk(). Each idiom arrived in a specific Python version, the newest in Python 3.14. One old-fashioned idiom pins the model at the version before that idiom existed, so this reading is deliberately strict.
Modern idioms
The same CLI tool as above.
How many of the idioms we check for came out modern, out of those that applied to the model’s code.
Newest Python it knows
Which Python release is the newest?
Roughly where the training data ends.
Lines touched for a tiny edit
Add a --verbose flag to a 40-line script.
How many lines changed. The minimal answer changes 7. Much more than that means it rewrote things nobody asked about.
Spots a made-up function?
How do I use itertools.flatten()?
That function doesn’t exist. Caught it means the model said so. Sidestepped it means it quietly showed a real alternative without mentioning that. Fell for it means it invented an answer.
Reasoning effort
The thinking setting we ran with. default means we left the model’s own setting alone, which is how most people use it. The token count is how much thinking the API reported.
Cost
What the API charged for all five tasks, in US dollars. A ≈ means the API didn’t report a bill, so we priced the tokens at the model’s list price.
The overview page calls the second row “Writes Python like it’s“, followed by a year: the release year of the Python version the code reads like.
New Model Drops? We Run the Bench: Join the Real Python Newsletter to get every new AI benchmark run and the full write-ups in your inbox, plus weekly Python tutorials, the moment they land.
Learning Path
Python Coding With AI
12 Resources ⋅ Skills: Cursor, Claude Code, AI-Assisted Development
The Results at a Glance
The run: anthropic/claude-fable-5.1 via OpenRouter, at its default reasoning settings, with no system prompt and nothing fixed up afterwards. Every task, one row, with the detail behind each number:
Task
Result
Detail
The snake
Drew it
772 drawing commands, 208 lines of code
How modern its Python is
Python 3.12 (2023)
pinned by path_copy; newest feature used: Python 3.12
Modern idioms
12 of 15
of the checkpoints that applied to its code
Newest Python it knows
3.14
the reply is quoted below
Lines touched for a tiny edit
13 (minimal: 7)
1.9× the minimal patch, 11 lines added and 2 removed
Spots a made-up function?
Caught it
said the function doesn’t exist and offered a real alternative
Reasoning effort
default
9.4k thinking tokens over all five tasks
Cost
$0.89
for all 5 tasks, as billed by the API
Wall time
3 min 36 s
17.5k output tokens
Read the full article at https://realpython.com/ai-benchmark-claude-fable-5-1/ »
[ Improve Your Python With 🐍 Python Tricks 💌 – Get a short & sweet Python Trick delivered to your inbox every couple of days. >> Click here to learn more and see examples ]
Read the full article at
Real Python AI
More in Tutorials & Guides
Your Model’s MSE Is Lying to You
First in a series on probabilistic forecasting for physical signals. Next: what happens when you roll the forecast forward more than one step. The post Your Model’s MSE Is Lying to You appeared first on Towards Data Science.
When to Use One Model and When to Use a Team of Agents
When Codex is the right shape for the problem, when Claude Code is, and how I split 5 specialist agents between them on dense AI capacity work. The post When to Use One Model and When to Use a Team of Agents appeared first on Towards Dat...
Agentic Engineering in Python: From Vibes to Evidence
Move from vibe coding to agentic engineering in Python, using tests, types, and code review to prove an AI agent's changes are safe to keep.
Graph Engineering for AI Agents: From Prompts and Loops to Workflows
A viral debate over loops versus graphs points to a bigger shift in how we build AI systems. Here’s what graph engineering actually means, how it differs from prompt, context, and loop engineering, and why it matters. The post Graph Engi...